Crawl budget: what it is and when it matters
Translated from the Spanish original. Leer en español

Google visits web pages to learn about their content and spot changes. Those visits are called crawling. How many pages it can and wants to check depends both on how your website responds and on Google's interest in its content. That is your crawl budget.
It matters most for large websites, frequently changing content, or a substantial backlog of pages Google knows about but has not crawled. On a small website, first check whether a crawling problem actually exists before looking for ways to increase its budget.
What Google's crawl budget means
Google cannot devote unlimited resources to every address on the internet. It decides which pages to visit and how often, within technical limits and according to its interest in checking them again.
It is not a fixed daily page allowance or a button that gets more pages into search results.
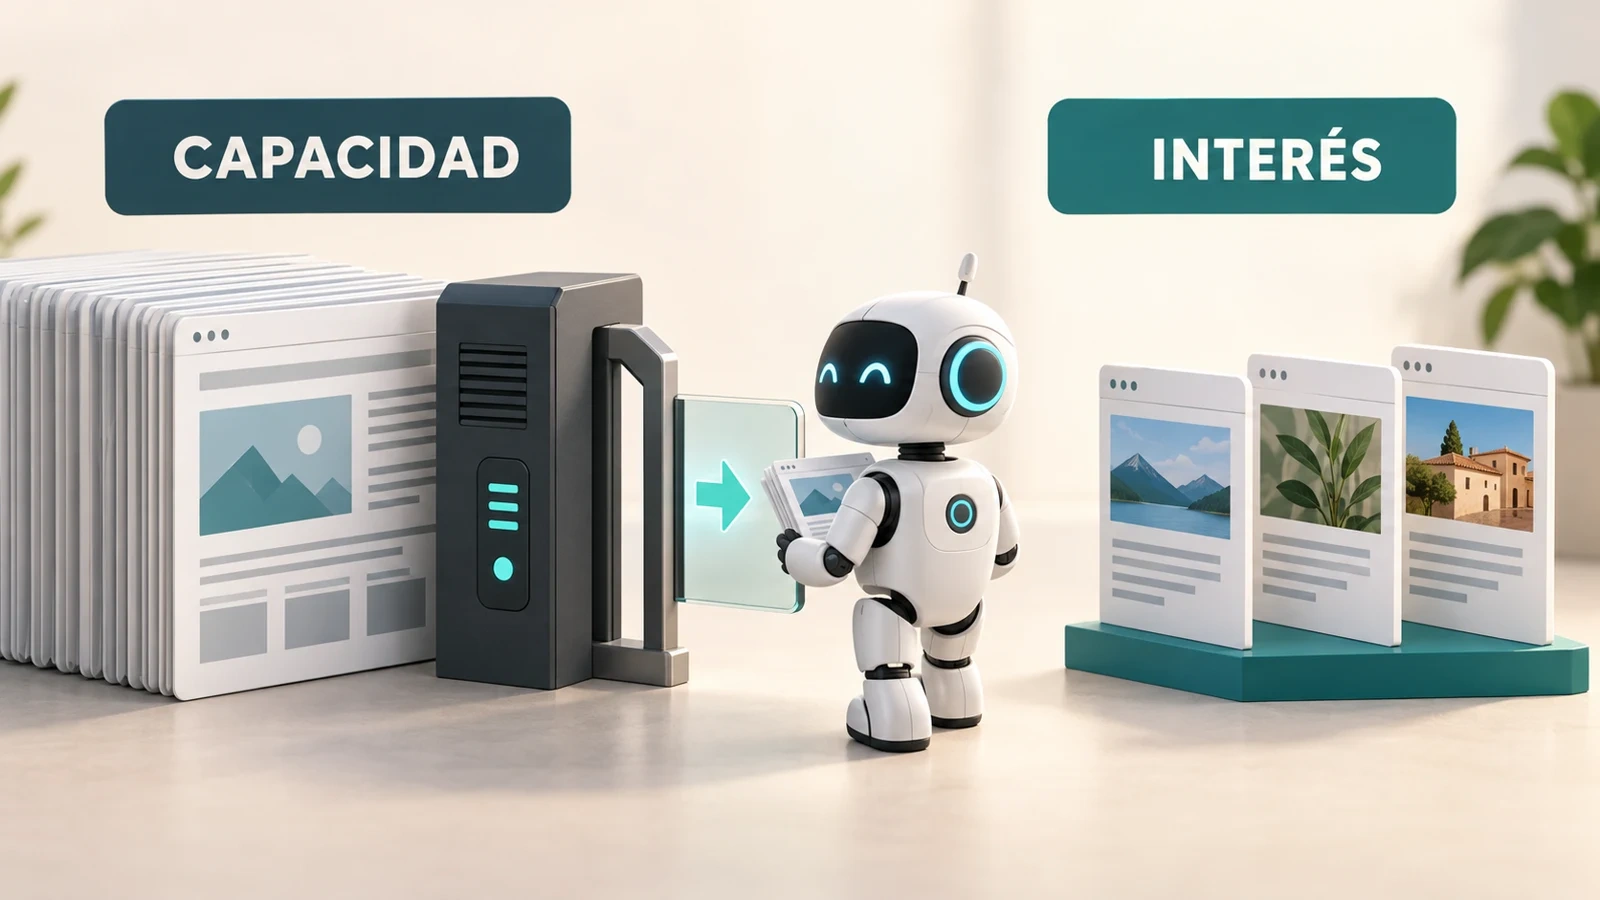
Google's crawl budget documentation distinguishes two components: crawl capacity and crawl demand. The first concerns what the server can handle. The second concerns the content Google wants to request.
The word budget can suggest a pot of a thousand Googlebot visits spent each morning. That is a misleading model. There is no universal number you can look up and divide manually among your pages.
Google defines a site here by its hostname: the specific name it connects to, such as www.example.com or shop.example.com. A main domain and a subdomain can be treated as separate sites for crawl-budget purposes. Check the property and host you are looking at before combining their data.
What determines a website's crawl budget
How many pages Google can visit without overloading your website
Crawl capacity is the technical limit on those visits. Google tries to crawl without overwhelming the website. Its limit takes connections and how long they remain open into account. Stable server responses may leave room to adjust that capacity. Slower responses or errors may reduce it.
The current guide names 5xx responses and rate-limiting signals such as HTTP 429 among the factors that can reduce capacity. Before asking for more robot visits, check whether the server handles the existing ones properly.
This does not mean every speed improvement will result in more crawling. Capacity might not be the constraint. The limit and the demand are different things.
Which pages Google wants to check and how often
Crawl demand is the interest in visiting particular pages. For Googlebot, Google's search crawler, factors include site size, update frequency, page quality, relevance and popularity. Google also works with the addresses it knows about, not only the ones you consider important.
A shop can have a manageable catalogue while generating many more addresses through filters and combinations. The question is not simply how many products exist. You need to understand how many different addresses the crawler encounters and what each one adds.
If demand is low, adding server resources does not force Google to visit more pages. Its crawl budget guide makes this explicit: crawling can remain low even when the capacity limit has not been reached.
When your website needs a review of Google's crawling
Google aims its advanced guide primarily at very large websites, medium or larger websites that change very frequently, and sites with a large proportion of URLs marked "Discovered - currently not indexed".
It gives a million pages with moderately frequent changes and ten thousand or more with very rapid daily changes as rough reference points. The documentation says these are estimates, not exact thresholds. Having 9,999 pages does not make a site immune; reaching ten thousand does not prove a problem.
A more useful check is whether important pages are crawled when published and whether changes are picked up normally. If so, there may be no bottleneck that warrants an advanced investigation.
The Crawl Stats report help also says sites with fewer than a thousand pages do not need to monitor crawling at that level of detail. This does not mean ignoring errors. It means spending time on the problem the evidence shows, rather than the one that sounds most technical.
Why a page Google has visited might not appear in search results
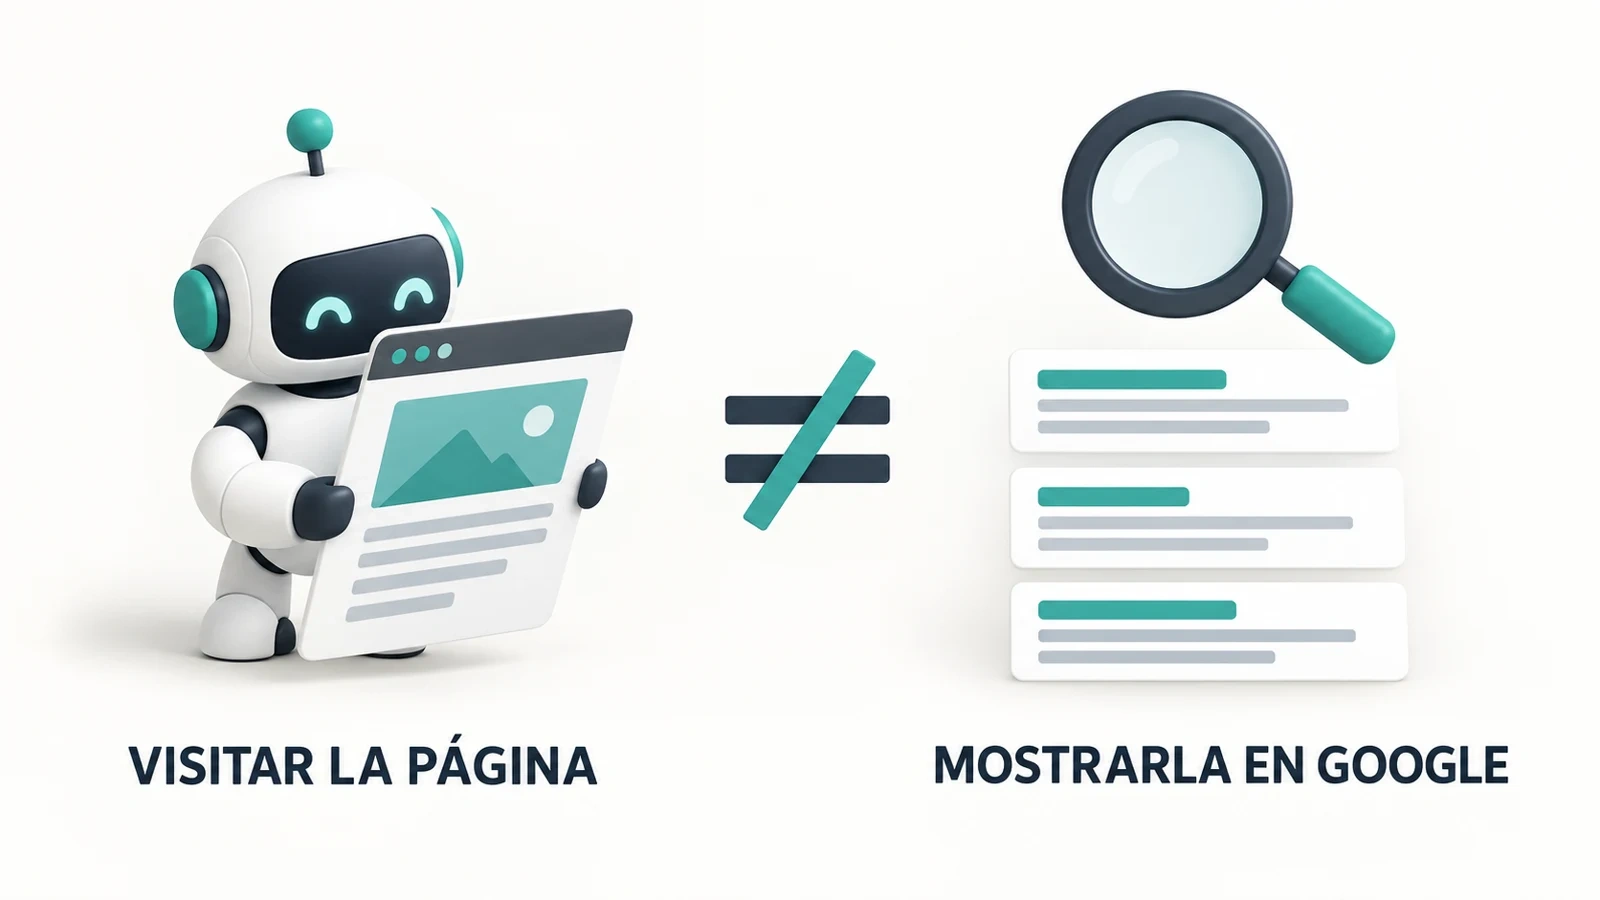
Crawling means requesting and processing the content. Indexing means deciding whether a page enters the index. One does not guarantee the other. Being indexed does not guarantee a particular ranking either.
The Page Indexing report separates reasons that should not be treated as the same fault.
- "Discovered - currently not indexed" means Google knows the address but has not crawled it yet.
- "Crawled - currently not indexed" means Google has crawled it but has not indexed it for now.
- A page excluded through a canonical, noindex or a proper removal needs that specific situation checked, rather than an assumption that the site lacks crawl budget.
This difference changes the diagnosis. If Google has already read a page, promising more crawling as an automatic solution to its absence from the index does not answer the evidence.
The Search Console beginner's guide explains where to find these reasons. Here, the point is to separate the stages before choosing what to investigate.
How to check Google's visits to your website in Search Console
How to check whether Google has trouble accessing your website
In Search Console, Google's tool for showing how it sees your website, open Settings and then Crawl Stats. The report shows whether Google has encountered problems reaching the site. If incidents appear, review robots.txt availability, DNS resolution and server connectivity rather than stopping at the chart's colour.
A resolved temporary fault is not the same as a recurring problem. Timing matters. Compare incidents with server changes, publication dates and technical changes that might have affected access.
How to compare Google's requests, errors and your website's response
The report shows requests, download volume and response time, with breakdowns by response and file type. These are clues for a hypothesis, not a score where more requests always means better.
If requests fall while response times and errors rise, there is a technical line to investigate. If requests fall without availability problems and the content barely changes, the chart's slope alone cannot support the same conclusion.
Why the example addresses do not show every Google visit
The Crawl Stats help explains that the URLs shown are a sample, not every request. An address missing from that sample is not proof that Google never requested it.
For a specific page, combine the report with URL Inspection. If you need a more detailed request analysis and have access to server logs, those logs can provide another perspective.
How to spot repeated addresses that Google needlessly visits
Start by comparing the pages you want Google to find with the addresses the website actually generates. They are not necessarily the same list.
Look for patterns: combinable filters, sorting options, parameters and repeated versions that create many addresses with little distinct content. The right decision depends on what each group does and whether it should appear in search. It is not a matter of blocking every parameter automatically.
Do not delete useful pages merely because they receive few visits. First distinguish a page with little value from one that is poorly connected. A review of orphan pages helps address discovery and navigation without confusing them with server capacity.
The aim is a sensible inventory. Thousands of repeated addresses are not necessarily fixed by asking the crawler to work faster.
What to use to stop Google visiting a page or showing it in results
Use robots.txt to prevent Google from visiting specific pages. Use noindex to ask that a page not appear in search results. Google must be able to access the page to read that instruction. Preventing a visit and excluding a result are separate decisions.
The documentation on blocking indexing with noindex warns that blocking the page first in robots.txt prevents Google from seeing the rule. Do not combine them mechanically to save crawling.
There is another important detail. The crawl budget guide advises against using robots.txt as a temporary way to shift resources between pages. Blocking a hundred addresses does not mean Google will spend a hundred visits on the ones you choose.
Google's crawling myths and facts also explain that noindex can have indirect effects on the inventory over the long term, but requires crawling to be detected. Its main purpose remains controlling indexing, not immediately regulating requests.
How to choose a fix and check whether Google's crawling improves
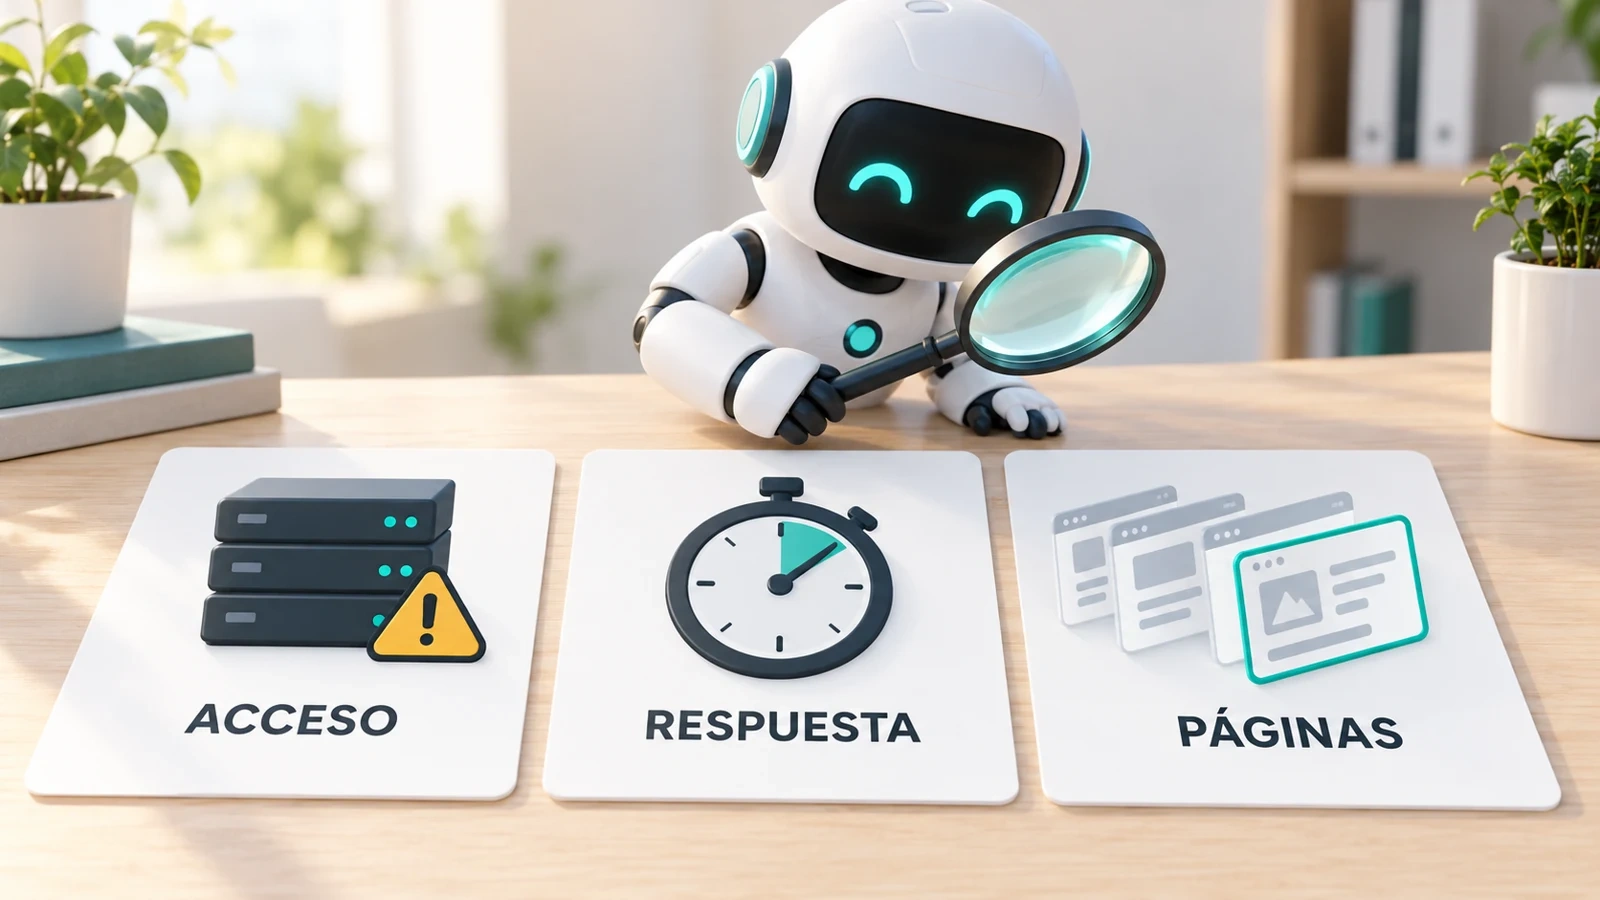
Write down the hypothesis before changing rules. "Google is not reaching new product pages and the server is returning errors" is something you can investigate. "We have too little crawl budget" is too broad a label for deciding changes.
Then define what should improve: availability, response time or access to particular groups of pages. Also check that important pages remain accessible and that reducing the inventory has not removed ways to discover them.
Requesting another crawl is not an unlimited solution either. Google says repeated requests for the same URL do not speed the process up, and requesting a crawl does not guarantee inclusion in search results.
In an SEO audit, this investigation helps decide where to act: server performance, URL generation, discovery or content assessment. Different diagnoses need different fixes. More requests without an improvement for important pages would not, by itself, be the outcome we want.
To finish your coffee
Crawl budget depends on what Google can crawl and what it wants to crawl. Before trying to increase it, check whether important pages remain unvisited, whether the server has problems, and whether the inventory is full of addresses that add no distinct content.
More crawling does not automatically mean more indexing. A sound decision starts by separating those two things.